98B
#1 of 14
parameters in ESM3 (2024), the most of 14 protein language models; the largest 2025 release, ProGen3, has 46B
What the chart shows
Protein language models learn from amino-acid sequences much as chatbots learn from text. The largest in the AI Index’s list is ESM3, released in 2024 with 98 billion parameters, followed by ProGen3 (2025, 46 billion) and ESM2 (2023, 15 billion).
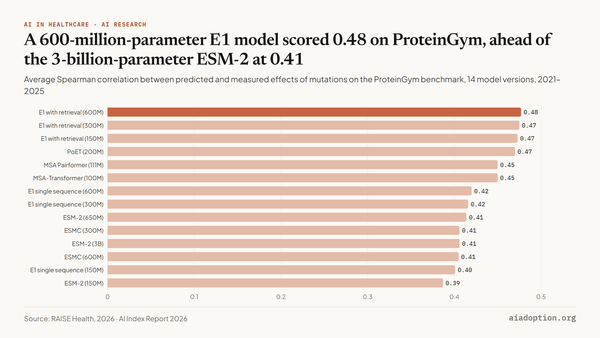
Other 2025 releases are far smaller: E1 has 600 million parameters, Proteina 400 million, PoET-2 182 million and SHIVER 43 million. The AI Index describes 2025 as a shift from scaling model size towards efficiency and specialisation.
Key numbers
| Measure | Value |
|---|---|
| ESM3 (2024) | 98 billion |
| ProGen3 (2025) | 46 billion |
| ESM2 (2023) | 15 billion |
| ProGen2 (2022) | 6.4 billion |
| E1 (2025) | 0.6 billion |
| SHIVER (2025) | 0.043 billion |
How to read it
- Selected models compiled by RAISE Health; not a complete list.
- The horizontal axis is logarithmic, so each gridline is ten times the one before.
- The data file dates MSA-Transformer to 2025; the AI Index’s ProteinGym data, in this hub, dates it to 2021.
Source: RAISE Health, 2026, via the AI Index Report 2026 (Stanford HAI), figure 6.1.5: Size of protein sequencing models, 2020–25. Chart and text by AI Adoption.
Numbers checked against the published data on 20 October 2026.
Download the data (CSV) · Cite this chart
Numbers checked against the published data on 20 October 2026.
Download the data (CSV) · Cite this chart


Discussion